
Google takes first and second in evaluation of AI doing professional work
U.S.-based Mercor, which provides AI evaluations and data, announced on Oct. 30 (early Oct. 31 Japan time) that Google's "Gemini 4 Carbon" ranked first on "APEX-Agents," an evaluation that has AI carry out the real work of investment banking analysts, management consultants and corporate lawyers. The share of tasks completed on the first attempt (Pass@1) was 84.2%, and the average share of grading criteria met was 90.4%. According to Mercor, Carbon is the only model with an average above 90%. Second place went to Gemini 4 Argon (82.4% Pass@1), whose availability Google also expanded in October, and third to Anthropic's Claude Sonnet 5.5 (75.5%). Before Carbon was added, Argon was in first place, so Google now holds the top two spots.
Gemini 4 Carbon debuts at #1 on APEX-Agents, and it's the only model on the leaderboard with a mean above 90%. 🥇Gemini 4 Carbon - 84.2% Pass@1, 90.4% mean 🥈Gemini 4 Argon - 82.4% Pass@1, 87.4% mean 🥉Claude Sonnet 5.5 - 75.5% Pass@1, 83.7% mean Google calls Carbon state-of-the-art…
- Gemini 4 Carbon
- Gemini 4 Argon
- Claude Sonnet 5.5
First in finance and consulting, Argon ahead in law
APEX-Agents is an evaluation that has AI complete long tasks spanning multiple apps, using files and tools placed in virtual workplaces. The current version, revised in September, poses 240 tasks across 31 virtual workplaces. Experts in each profession create the tasks and grading criteria, and another AI grades the deliverables against those criteria.
Mercor recruits experts to supply training data to AI companies, and it was reported to have exceeded $2 billion in annualized gross revenue in June 2026. In October 2025, it raised $350 million at a $10 billion valuation.
By profession, Carbon ranked first for both management consultants, at 91.9%, and investment banking analysts, at 86.9%. For corporate lawyers, it scored 73.8%, second to Argon's 76.7%.
- Gemini 4 Carbon
- Gemini 4 Argon
Lead within margin of error, fourth on another evaluation
The gap between first and second place is small. Mercor gives a margin of error of ±4.3 points on Pass@1 for both Carbon and Argon, and the 1.8-point gap falls within that range. Reasoning settings also differ between models. The Google models were measured at "High," while Anthropic's were measured at the deepest setting, "Max."
On another third-party evaluation measuring the same kind of work, Carbon does not hold first place. On "AA-Briefcase," in which Artificial Analysis compares models by assigning real work such as preparing documents, Carbon scored 1609, behind China's Moonshot AI's Kimi K3.1 Pro (1678), Meta's Muse Wonder (1659) and xAI's Grok 4.7 (1638). That was a big improvement on Argon's 1483. The scores are relative ratings calculated from wins and losses when models' deliverables are compared head to head, and there is no maximum score.
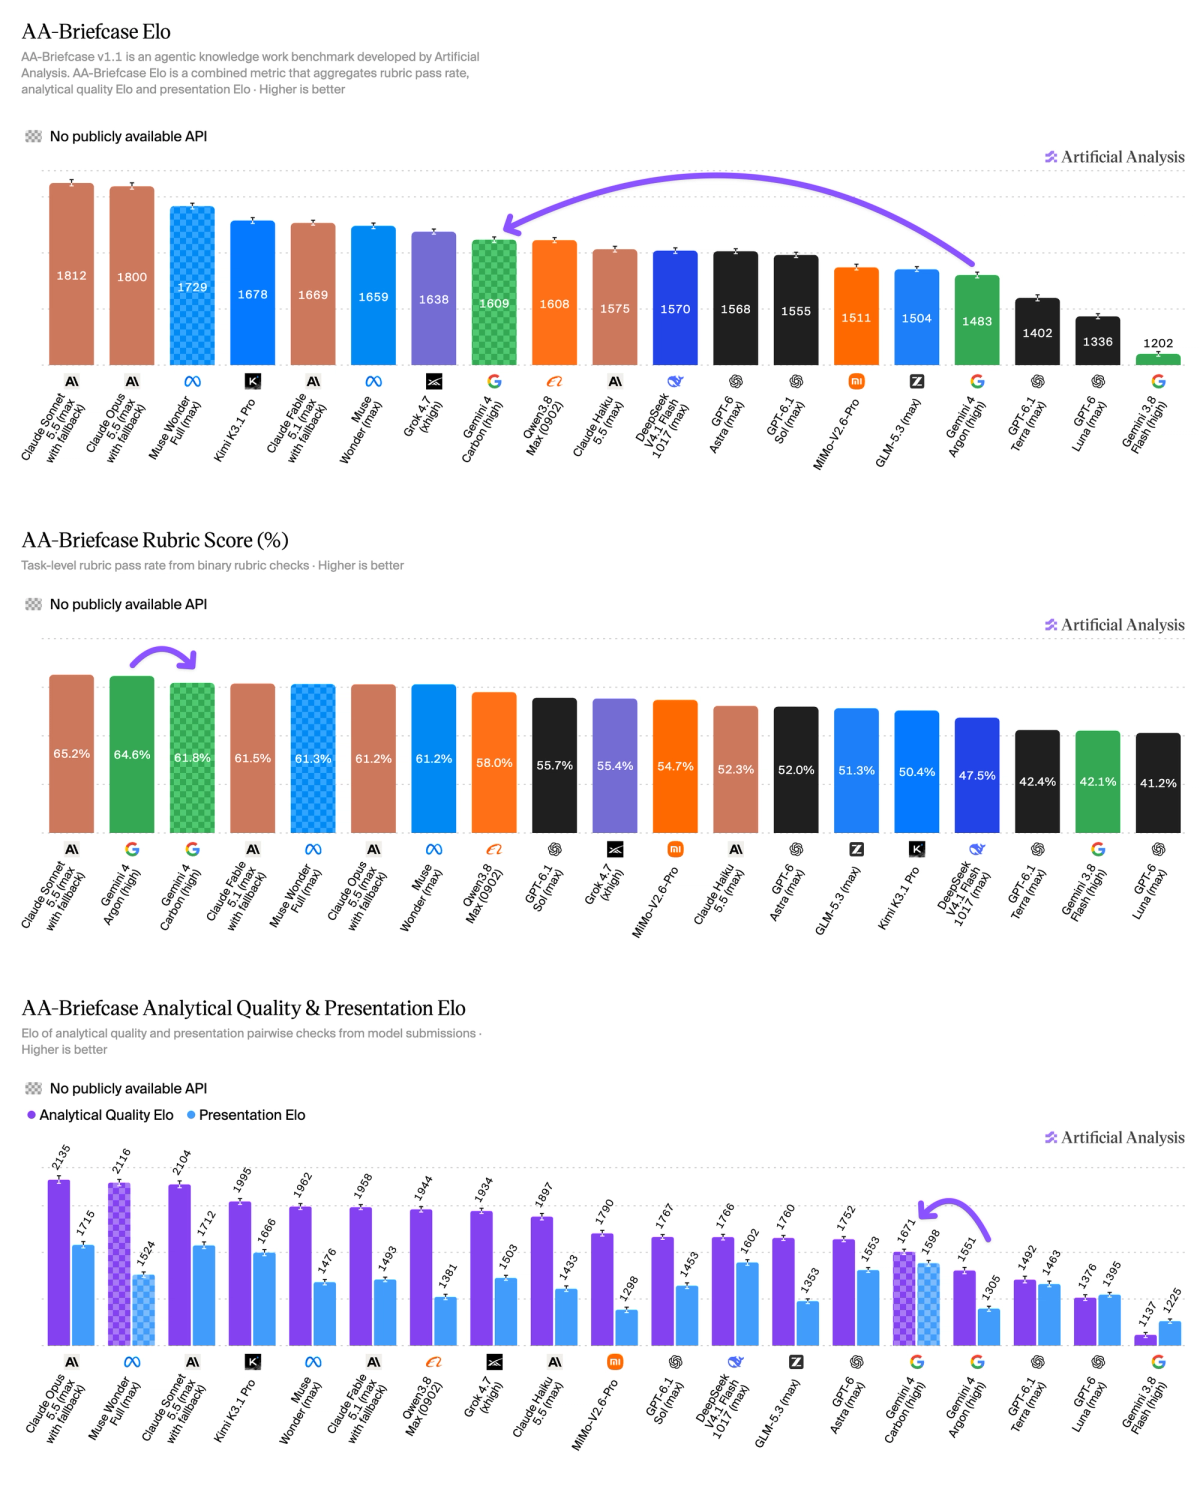
On "Finance Agent," in which evaluation company Vals AI measures AI carrying out financial work, Carbon also ranked fifth of 35 models (67.16%). On the other hand, it ranked first of 89 models on the company's legal research evaluation, "Legal Research Bench."
According to Artificial Analysis, its rate of producing wrong answers on evaluations of factual questions was 11%, up from Argon's 4%.
Pricing and availability
Carbon is currently offered only to cyber defense organizations vetted by Google. Availability to developers, businesses and general users is promised as soon as possible, with no date given.
API pricing per million tokens during the introductory period is $2 for input and $10 for output, the same as Argon. After the introductory period, it will be $4 for input and $20 for output. The cost for Artificial Analysis to run its overall evaluation at standard prices was $7.76 per task, below Anthropic's Claude Opus 5.5 ($10.04) and above OpenAI's GPT-6 Astra ($6.25). Argon cost $7.68. According to Artificial Analysis, Carbon output 123,000 tokens of text per task, below Opus 5.5's 173,000.
Post reports testing of improved "Carbon-H"
On Oct. 31, a post said that "Gemini 4 Carbon-H," seen as an improved version, was appearing under the name "Argon 4" on Arena, a site that compares AI models anonymously. Google has made no announcement about this version.


